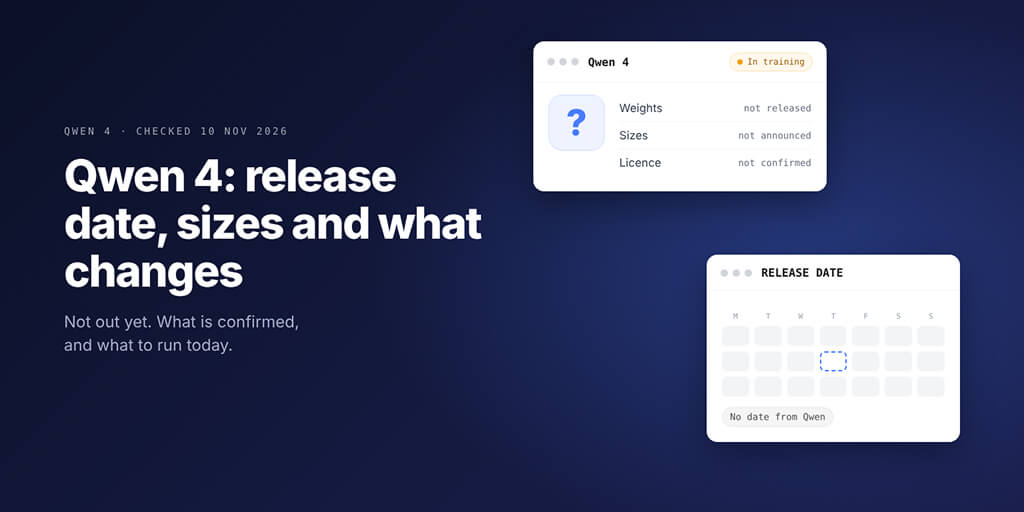
Not out yet. Here is what Qwen has put in writing, what its own code hints at, and what to run until it lands.
| Question | Answer on 10 November 2026 |
|---|---|
| Is Qwen 4 out? | No. No Qwen 4 weights from Qwen on Hugging Face, GitHub or Ollama |
| Release date? | None published. Alibaba: "currently in training" |
| Open weight? | Reported, not in Alibaba's own announcements |
| Qwen 4 27B? | The name is reported, not confirmed |
| What to run today | qwen3.8:27b in Ollama, an 18GB download |
Picture this: you search Hugging Face for Qwen4-27B and get a full page of hits, all uploaded the same evening.
Finally.
You open one. Two files: a .gitattributes and a README that says placeholder, no weights yet.
That's where Qwen 4 stands right now: plenty of names, no model. We checked Qwen's research page, its Hugging Face organisation, its GitHub and the Ollama library on 10 November 2026, and this page sticks to what those sources show. We'll rewrite it in place the day Qwen 4 ships.
Is Qwen 4 out? Not yet
No. Qwen's research page lists nothing newer than Qwen-Image-2.1 on 20 September. The Qwen organisation on Hugging Face has no Qwen4 repository, and Ollama's library has no qwen4 page.
You can check it yourself in ten seconds:
# Qwen's own Hugging Face org: [] means no Qwen4 repos yet
curl -s "https://huggingface.co/api/models?author=Qwen&search=Qwen4"

# Ollama library page: 404 means it is not there yet
curl -s -o /dev/null -w "%{http_code}\n" https://ollama.com/library/qwen4
Look at the publisher, not just the name. Anyone can create a repo called Qwen4-27B, and the only Qwen 4 that counts comes from the Qwen account.
What Qwen has confirmed about Qwen 4
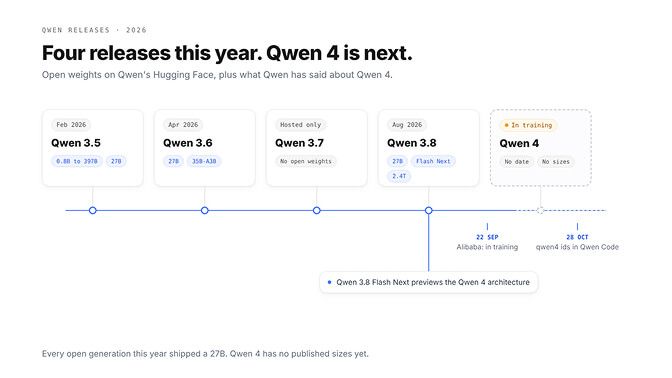
Less than the headlines suggest. Alibaba's press release from the Apsara Conference, dated 22 September 2026, says Qwen 4 "is currently in training." It names no sizes, no date and no licence.
The same release sketches what comes after: the Qwen 4.5 and Qwen 5 series are projected to scale to 5 to 10 trillion parameters. For scale, the biggest open Qwen model today, Qwen3.8-2.4T-A95B, has 2.4 trillion.
The most concrete Qwen 4 fact sits on a model card, not in a launch post. Qwen's Hugging Face card for Qwen3.8-Flash-Next calls it an "experimental preview of the architecture that will underpin Qwen4." That design pairs Gated DeltaNet with a new Qwen Sparse Attention, adds gated residuals and an n-gram embedding, and runs 125B parameters with only 6B active per token.
If you want to know how Qwen 4 will behave, don't wait for the launch post. Flash Next is the preview, and you can download it today.
Our Gemma 4 vs Qwen 3.8 breakdown covers Flash Next's benchmarks and memory needs next to every Gemma 4 size.
What about open weights? Press reports say the head of the Qwen team stated that Qwen 4 and Qwen 5 will keep shipping as open-weight models. We could not find that statement in Alibaba's own announcements, so treat it as reported until Qwen puts it in writing.
A teaser poster went out on 6 November, according to press coverage, with no model name, date or specs. Rumoured release dates are everywhere. None of them come from Qwen.
What Qwen's own code suggests (unconfirmed)
Here's the change that set off the speculation. Qwen Code, Qwen's open-source coding agent, merged a commit titled "fix(core): size the qwen4 generation at 1M". It's pull request #15762 in the QwenLM/qwen-code repository on GitHub, dated 28 October 2026, and it's in the main branch today.
The change is one rule in the file that sets context windows:
// 1M is the forward default for the qwen4 generation, so qwen4.x releases
// need no further code change.
[/^qwen4/, LIMITS['1m']],
The tests added with it name these ids: qwen4, qwen4-max, qwen4-plus, qwen4-coder-plus, qwen4.5-max and qwen4-max-2026-10-01.
Read them as code references, not a product list. Three cautions before you quote them:
- They are test strings. They show Qwen's tooling expects a qwen4 family, not that any of those exact models exist.
- The 1M window is a "forward default" in the code's own words. The same file already gives qwen3.x API models 1M, so it says nothing new about Qwen 4's context.
qwen4-max-2026-10-01is a date-stamped example id. It is not a release date, and 1 October has already passed.
Other ids you may see quoted, such as an omni or "think" variant, are not in this pull request, so we left them out.
Qwen 4 sizes and the 27B question
Nothing official yet. Press reports list four names, Qwen4-Max, Qwen4-Plus, Qwen4-Flash and Qwen4-27B, but Alibaba's published materials name none of them. If you're choosing a 27B-class model right now, our Gemma 4 31B vs Qwen 3.8 27B comparison runs the two dense models side by side.
The 27B guess has history behind it, though. Here's what Qwen has shipped as open weights this year:
| Generation | Open sizes on Qwen's Hugging Face | Released |
|---|---|---|
| Qwen 3.5 | 0.8B, 2B, 4B, 9B, 27B, 35B-A3B, 122B-A10B, 397B-A17B | February 2026 |
| Qwen 3.6 | 27B, 35B-A3B | April 2026 |
| Qwen 3.7 | None (hosted Qwen3.7-Plus only) | Hosted only |
| Qwen 3.8 | 27B, Flash Next (125B, 6B active), 2.4T-A95B | August 2026 |
| Qwen 4 | Not announced | Not announced |
27B is the only size in every open generation this year. It's also the size that fits a 24GB card: Ollama's default qwen3.8:27b download is 18GB. That's why people search for a Qwen 4 27B, and why we'd bet on one too. A bet, not a fact.
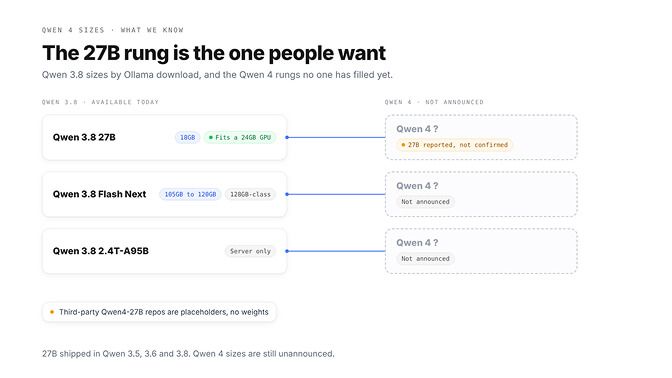
One warning about those Qwen4-27B uploads on Hugging Face. They come from a third-party account, they're tagged placeholder, and there are no weights inside. Don't build a download script around them.
Qwen 4 vs Qwen 3.8: what would make it worth upgrading
Qwen 3.8 already set a high bar. On Qwen's own model cards, the 27B went from 63.4 to 73.0 on Terminal Bench 2.1 and from 53.5 to 61.7 on SWE-bench Pro between Qwen 3.6 and 3.8. These are vendor-reported numbers on Qwen's own setup, so read them as direction, not decimals.
Benchmarks aren't the whole story, though. Thinking is the quiet cost: Qwen 3.8 keeps reasoning from every earlier turn by default, and in a 30-step agent loop that piles up fast. If your agent stalls or balloons on Qwen 3.8 today, read our Qwen 3.8 27B tool calling fix first, because most of those problems will follow you to Qwen 4.
So what would make Qwen 4 worth the switch for an agent? Here's our checklist:
| Area | Qwen 3.8 today | Worth upgrading if Qwen 4... |
|---|---|---|
| Context | 262K native, extensible to about 1M | Gives you 1M natively on the open sizes |
| Long-context speed | 27B is a dense model | Brings the Flash Next attention to the 27B class |
| Tool calling | 27B: 67.1 on Toolathlon Verified | Matches Flash Next's 73.5 at 27B size |
| Thinking | On by default, preserve_thinking on | Spends fewer tokens per agent step |
| Licence | 27B Apache 2.0, Flash Next custom | Keeps Apache 2.0 on the sizes you run |
The Flash Next numbers are the tell. With 6B active parameters it scores 62.5 on SWE-bench Pro and 73.5 on Toolathlon Verified, against 61.7 and 67.1 for the dense 27B. The architecture Qwen 4 is built on already does more with less.
The question for Qwen 4 isn't "is it smarter?" It's "does it fit my GPU, keep the licence I need, and call tools without eating my context?"
What to run today: Qwen 3.8 27B, 3.8 Flash Next or Gemma 4 31B
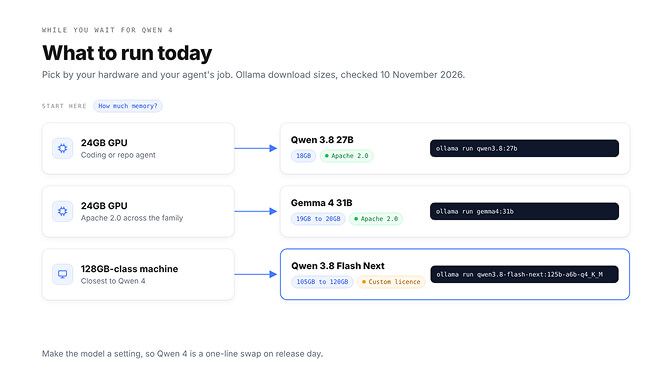
Waiting costs you weeks of agent work for a model with no date. Here's what Ollama serves right now:
| Model | Ollama tag | Download | Context | Licence |
|---|---|---|---|---|
| Qwen 3.8 27B | qwen3.8:27b | 18GB | 256K | Apache 2.0 |
| Qwen 3.8 Flash Next | qwen3.8-flash-next:125b-a6b-q4_K_M | 120GB | 256K | Qwen Community |
| Gemma 4 31B | gemma4:31b | 19GB to 20GB | 256K | Apache 2.0 |
Our picks:
- 24GB GPU and a coding or repo agent: Qwen 3.8 27B.
- 24GB GPU and you need Apache 2.0 across the whole family: Gemma 4 31B.
- 128GB-class machine: Flash Next, the closest thing to Qwen 4 you can run. Read its licence first. Ollama also lists a 105GB MLX build.
Whichever you pick, set things up so the model is a setting, not a rebuild. The day Qwen 4 lands, you'll want to try it on one agent before you move the rest.
On BetterClaw every agent runs on the model you choose, with your own API keys across 28+ providers at zero markup, and BetterClaw Desktop connects the Ollama models on your machine to your cloud agents. Switch one agent to Qwen 4, compare a week of its runs against Qwen 3.8, then decide. Plans start from $19 a month, and your first workspace starts with a 7-day free trial. See BetterClaw plans
Flash Next is the interesting one. Since Qwen says its architecture will underpin Qwen 4, running it now shows you how the next generation behaves in your own agent loops.
Running Qwen 3.8 27B in Ollama: the settings that matter
If you go with Qwen 3.8 27B, a few minutes of setup decides whether it behaves like an agent model or a slow chatbot. These are the official qwen3.8 tags in the Ollama library on 12 November 2026, all with a 256K context window and text plus image input:
| Tag | Download | Fits |
|---|---|---|
qwen3.8:27b (same as latest), 27b-q4_K_M, 27b-mtp-q4_K_M | 18GB | 24GB GPU, 24GB+ Mac |
qwen3.8:27b-mlx | 18GB | Apple Silicon with 24GB+ |
qwen3.8:27b-q8_0, 27b-mtp-q8_0, 27b-mxfp8 | 30GB | 32GB+ GPU or Mac |
qwen3.8:27b-bf16, 27b-mlx-bf16 | 56GB | 64GB+ |
It still runs on a 16GB card, but Ollama spills layers to system RAM and generation slows sharply. Run ollama ps while the model is loaded: the PROCESSOR column shows the GPU and CPU split.
Raise the context window. Ollama does not give a model its full context by default. It allocates 4K below 24GiB of VRAM, 32K from 24 to 48GiB, and 256K only from 48GiB up, and its docs recommend at least 64K for agents and coding tools. A 4K window is the most common reason a local agent forgets its instructions or calls the wrong tool. Set it in a Modelfile:
FROM qwen3.8:27b
PARAMETER num_ctx 65536
PARAMETER num_predict 8192
PARAMETER temperature 1.0
PARAMETER top_p 0.95
PARAMETER top_k 20
Build it with ollama create qwen38-agent -f qwen38-agent.modelfile. The sampling values are the model card's settings for thinking mode. Thinking tokens count toward num_predict, so set it too low and answers stop mid-sentence. Leave the repetition penalty at 1.0, as the card recommends, rather than copying repeat_penalty 1.1 from older Qwen guides.
Switch thinking off for routine turns. Thinking is on by default. For classification, extraction and routing it mostly costs time and tokens. Use --think=false on the command line, /set nothink in a session, or "think": false on /api/chat. With thinking off, the card recommends temperature 0.7, top_p 0.8 and presence_penalty 1.5.
Prefer the native API path. Ollama's library page now offers ollama launch openclaw --model qwen3.8 and ollama launch hermes --model qwen3.8 to wire up an agent in one command. If you connect a framework by hand, use its native Ollama provider on /api/chat rather than the OpenAI-compatible /v1 endpoint where you have the choice: an early Ollama report of /v1/chat/completions hanging on qwen3.8:27b, while /api/chat worked, was closed without a fix.
If you're still on Qwen 3.7. There is nothing to pull. Qwen3.7-Max and Qwen3.7-Plus were hosted-only, ollama.com/library/qwen3.7 still returns a 404, and the open-weight line skipped straight to 3.8. If you used 3.7 through an API, Qwen 3.8 27B is the local replacement, and qwen3.6:27b remains in the Ollama library as a fallback.
Will Qwen 4 run in Ollama on day one?
Maybe, and there's a good sign. Ollama needs engine support for a model's architecture before it can list it, and for a brand-new design that work takes time.
Qwen 4 has a head start. Ollama already serves Flash Next, the architecture preview, and its library page repeats Qwen's line about the architecture behind Qwen4. If Qwen 4 keeps that design, much of the engine work is done; that's our reading, not a promise from Qwen or Ollama.
Here's the release-day check we'll run:
# 1. Is there an official library page yet? (200 means yes)
curl -s -o /dev/null -w "%{http_code}\n" https://ollama.com/library/qwen4

# 2. Pull the exact tag shown on that page, then look for "tools" under Capabilities
ollama pull qwen4
ollama show qwen4
The qwen4 tag above is our guess. Copy the real one from the library page.
A model that loads isn't automatically a model your agent can use. Before you wire it into anything, confirm it calls tools; our list of Ollama models with tool calling support shows what to check and how.
The model you can run beats the model you're waiting for
Qwen has put three things about Qwen 4 in writing: it's in training, Flash Next previews its architecture, and Qwen's own tools already make room for the name.
Everything else, the date, the sizes, the licence, is still a rumour with a nice font.
So run Qwen 3.8 now, keep your agent's model a one-line change, and keep a small test set ready. Write down the five jobs your agent does most, with the answer you expect for each. That's your test set, and it takes ten minutes.
When Qwen 4 ships, the team with tests ready decides in an afternoon. Everyone else spends the week reading launch posts.
Frequently Asked Questions
When is Qwen 4 coming out?
Qwen has not published a date. Alibaba said on 22 September 2026 that Qwen 4 is "currently in training", and every specific date circulating since then comes from rumour, not from Qwen. We will update this page on release day.
Is there a Qwen 4 27B?
Not yet. A Qwen4-27B name appears in press reports, but Alibaba has not confirmed it, and the Qwen4-27B repos on Hugging Face are third-party placeholders with no weights. A 27B is likely, because it is the only size Qwen shipped as open weights in Qwen 3.5, 3.6 and 3.8.
Will Qwen 4 be open source?
That is reported, not confirmed. Press reports quote the head of the Qwen team saying Qwen 4 and Qwen 5 will keep shipping as open-weight models, but Alibaba's own announcements do not say so. Even then, check the licence per size: Qwen 3.8 27B is Apache 2.0, while Flash Next and the 2.4T model use custom licences.
Qwen 4 vs Qwen 3.8, what is new?
Nothing is confirmed beyond the architecture. Qwen says Qwen3.8-Flash-Next previews the design that will underpin Qwen 4: Qwen Sparse Attention, gated residuals and an n-gram embedding, with 6B active parameters out of 125B. Sizes, benchmarks and context length for Qwen 4 have not been published.
Can I run Qwen 4 in Ollama?
Not yet: ollama.com/library/qwen4 returns a 404 today. When it lands, pull the tag shown on the library page and check that ollama show lists tools before you connect an agent. Ollama already runs Flash Next, the Qwen 4 architecture preview, which is a good sign for quick support.
What should I run until Qwen 4 is released?
Run Qwen 3.8 27B (qwen3.8:27b, 18GB) on a 24GB GPU for coding and agent work, or Gemma 4 31B if you need Apache 2.0 across the whole family. On a 128GB-class machine, Qwen 3.8 Flash Next is the closest preview of Qwen 4 you can run today.